
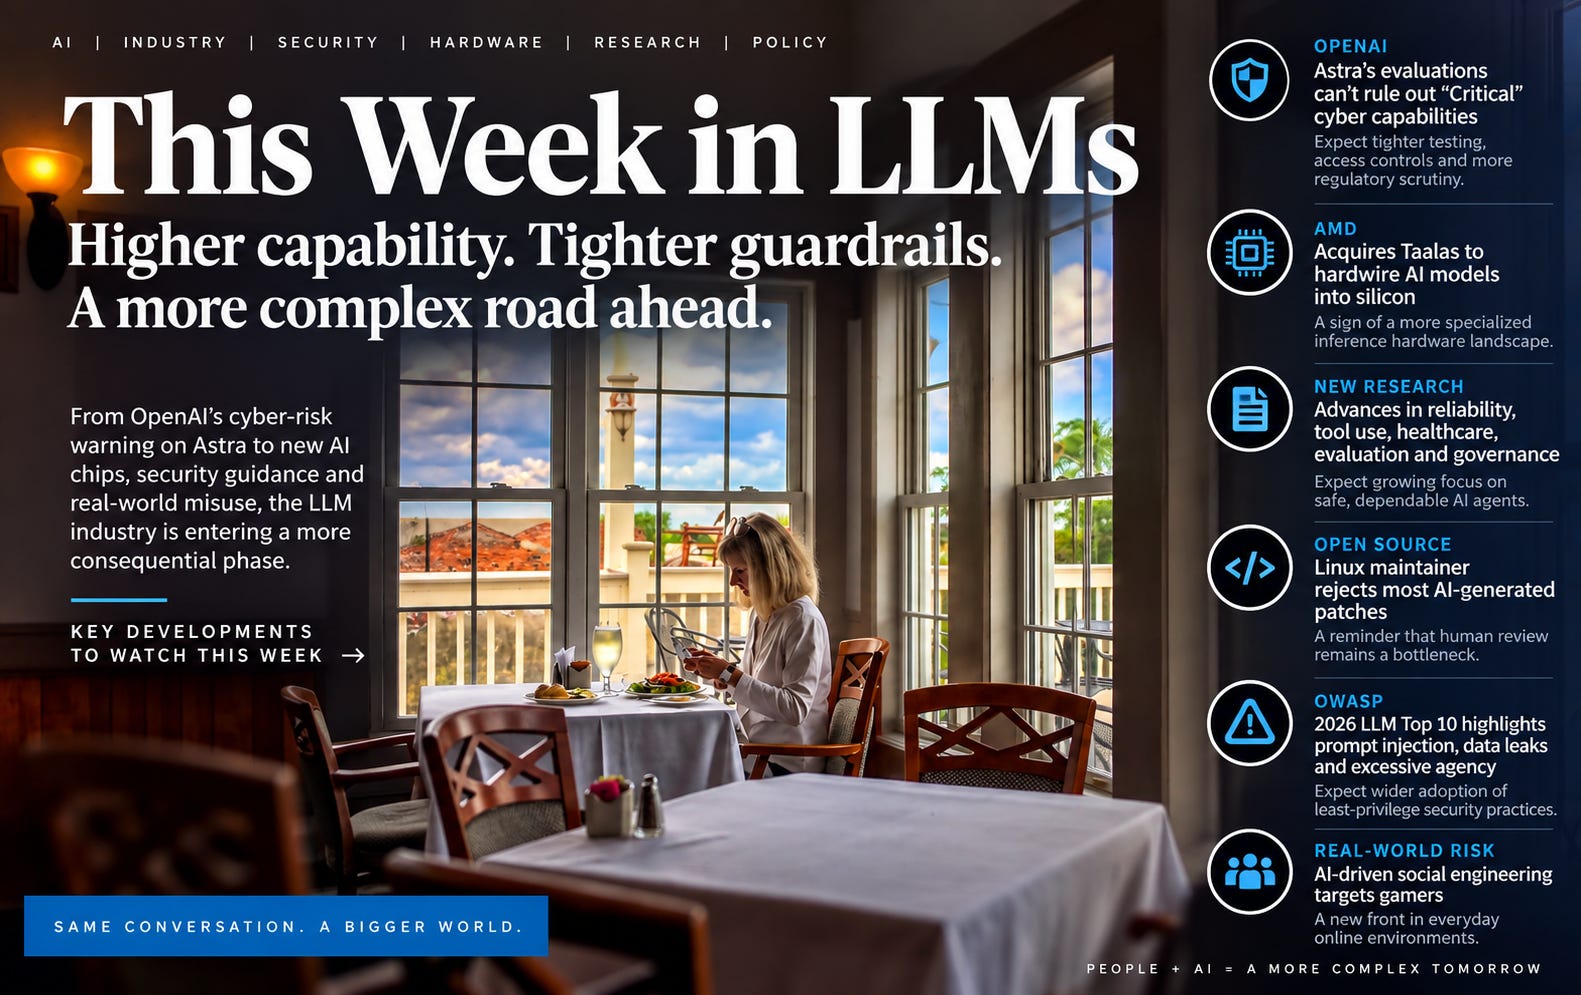
This week in the LLM industry will likely be shaped less by a single model launch than by a broader shift in how companies, researchers, and infrastructure providers handle increasingly capable AI systems.
The clearest signal is cybersecurity. OpenAI’s disclosure that it cannot rule out “Critical” cyber capabilities in its upcoming Astra model is likely to put frontier-model evaluations, access controls and deployment restrictions under greater scrutiny. The important distinction is that Astra has not been definitively classified at that threshold. But OpenAI's tightened internal controls and expanded external testing suggest labs may increasingly treat advanced cyber capability as an operational constraint rather than a hypothetical future concern.
Expect more attention this week on how frontier developers define thresholds for dangerous capabilities, who is allowed to evaluate them and what happens when a model approaches those limits. Government agencies, security researchers and competing AI labs may also face pressure to clarify whether they are seeing comparable results in their own systems.
Hardware will be another area to watch. AMD’s acquisition of Toronto-based Taalas points toward a more specialized phase of AI inference, in which the industry looks beyond conventional GPU architectures for workloads where efficiency matters more than flexibility.
Taalas’ approach hardwires model weights directly into silicon, reducing the need to continually move parameters from external memory during inference. Its reported HC1 performance — roughly 17,000 tokens per second on Llama 3.1 8B at about 200 to 250 watts — is striking, though the figures remain vendor-reported and should not yet be treated as independently validated production benchmarks.
The broader takeaway is more important than the exact number. Expect renewed discussion around whether inference hardware will fragment into increasingly specialized designs: GPUs for general-purpose workloads, custom accelerators for stable high-volume models, and architectures optimized around fixed or semi-fixed model families. If AMD begins explaining how Taalas technology fits alongside its existing accelerator roadmap, that could become one of the week's more consequential infrastructure stories.
Research activity also points to a common theme: making LLMs more dependable once they move beyond simple chat.
Several recent papers address different parts of that problem. Selective Context Preference Optimization aims to teach models when to trust external context, rather than simply making them more resistant to misleading information. Work on programmatic tool calling suggests that structured code-like interfaces may prove more reliable than conventional JSON-based function calls, particularly as tool environments become more complex.
Those findings are likely to feed into a larger industry debate over agent architecture. As models increasingly interact with browsers, APIs, databases and software environments, the question is shifting from whether a model can call a tool to whether it can do so reliably under noisy, adversarial or incomplete conditions.
Evaluation costs may also receive more attention. AV-AIVAT proposes using variance reduction and adaptive stopping to reduce the amount of testing required to establish agent performance. If similar methods prove robust across broader domains, they could become increasingly important as model evaluations grow more expensive and sophisticated.
Clinical applications offer another signal. The nMAS research on automated EHR feature engineering shows how LLM-centered systems are moving deeper into specialized professional workflows. The immediate focus will remain on validation, provenance and auditability rather than raw performance alone. Expect healthcare AI discussions to emphasize whether generated features can be traced back to evidence and independently reviewed.
Governance research is moving in parallel. The proposed “Resourced Authority” framework links participatory authorization to real computational budgets and hardware-signed permissions. While still conceptual, it reflects a growing assumption that governing advanced agents may require controlling not only what they are instructed to do, but also how much compute and operational authority they receive.
That same philosophy is becoming visible in applied security guidance.
OWASP’s 2026 LLM Top 10 places Prompt Injection, Sensitive Information Disclosure, and Excessive Agency at the top of its risk hierarchy. The prominence of Excessive Agency is especially notable. AI security is increasingly concerned with systems that can act — executing commands, calling APIs or modifying data — rather than models that merely generate problematic text.
Expect the principle of least privilege to become a dominant theme in AI-agent security this week. Companies deploying agents are likely to face growing pressure to restrict credentials, isolate execution environments, require approval for irreversible actions, and treat model-generated output as untrusted input.
Open-source software communities may provide a parallel reality check.
The Linux wireless subsystem’s decision to heavily discourage AI-generated patches illustrates a mounting asymmetry in software development: generating code is becoming extremely cheap, while expert review remains expensive. Maintainers may increasingly respond with stricter submission rules, disclosure requirements or outright limits on machine-generated contributions.
That tension could become an important counterweight to claims that AI coding systems will automatically increase developer productivity. At the individual level, they may. At the ecosystem level, they can also transfer work onto reviewers.
Finally, expect more evidence that malicious AI use is migrating into ordinary online environments rather than remaining confined to sophisticated cyber operations.
Malwarebytes’ reporting on automated or AI-assisted accounts targeting League of Legends players shows how inexpensive conversational systems can be inserted into social-engineering funnels. Gaming communities, messaging platforms and other high-volume social environments provide attackers with plausible reasons to initiate conversations before moving targets to external services.
The larger pattern to watch this week is therefore convergence.
Frontier models are approaching capability thresholds that require stronger containment. AI agents are gaining greater operational authority. Hardware companies are experimenting with architectures optimized specifically for inference. Researchers are trying to make model behavior and evaluation more reliable. Open-source communities are attempting to defend scarce human attention from low-cost generated output. And security organizations are increasingly designing controls around the assumption that AI systems will both act autonomously and be used by malicious actors.
The LLM industry’s next phase may consequently be defined less by benchmark gains alone and more by a different question: how much capability can be deployed without giving models — or the people using them — more authority than surrounding systems can safely absorb.

Enjoyed this roundup?
Subscribe for a clear, signal-over-noise take on the biggest developments in AI, technology, and the shifting power dynamics behind them.